Home Services SysAdmin & Security
The night shift
Your servers, watched around the clock.
Managed infrastructure, 24/7 monitoring, and incident response from engineers who have paged through every failure mode — and automated away most of them. When something breaks at 3am, we already know.
- 24/7 monitoring
- Incident response
- Hardening
- Backup & DR
Managed infrastructure
Run your business. We'll run the servers.
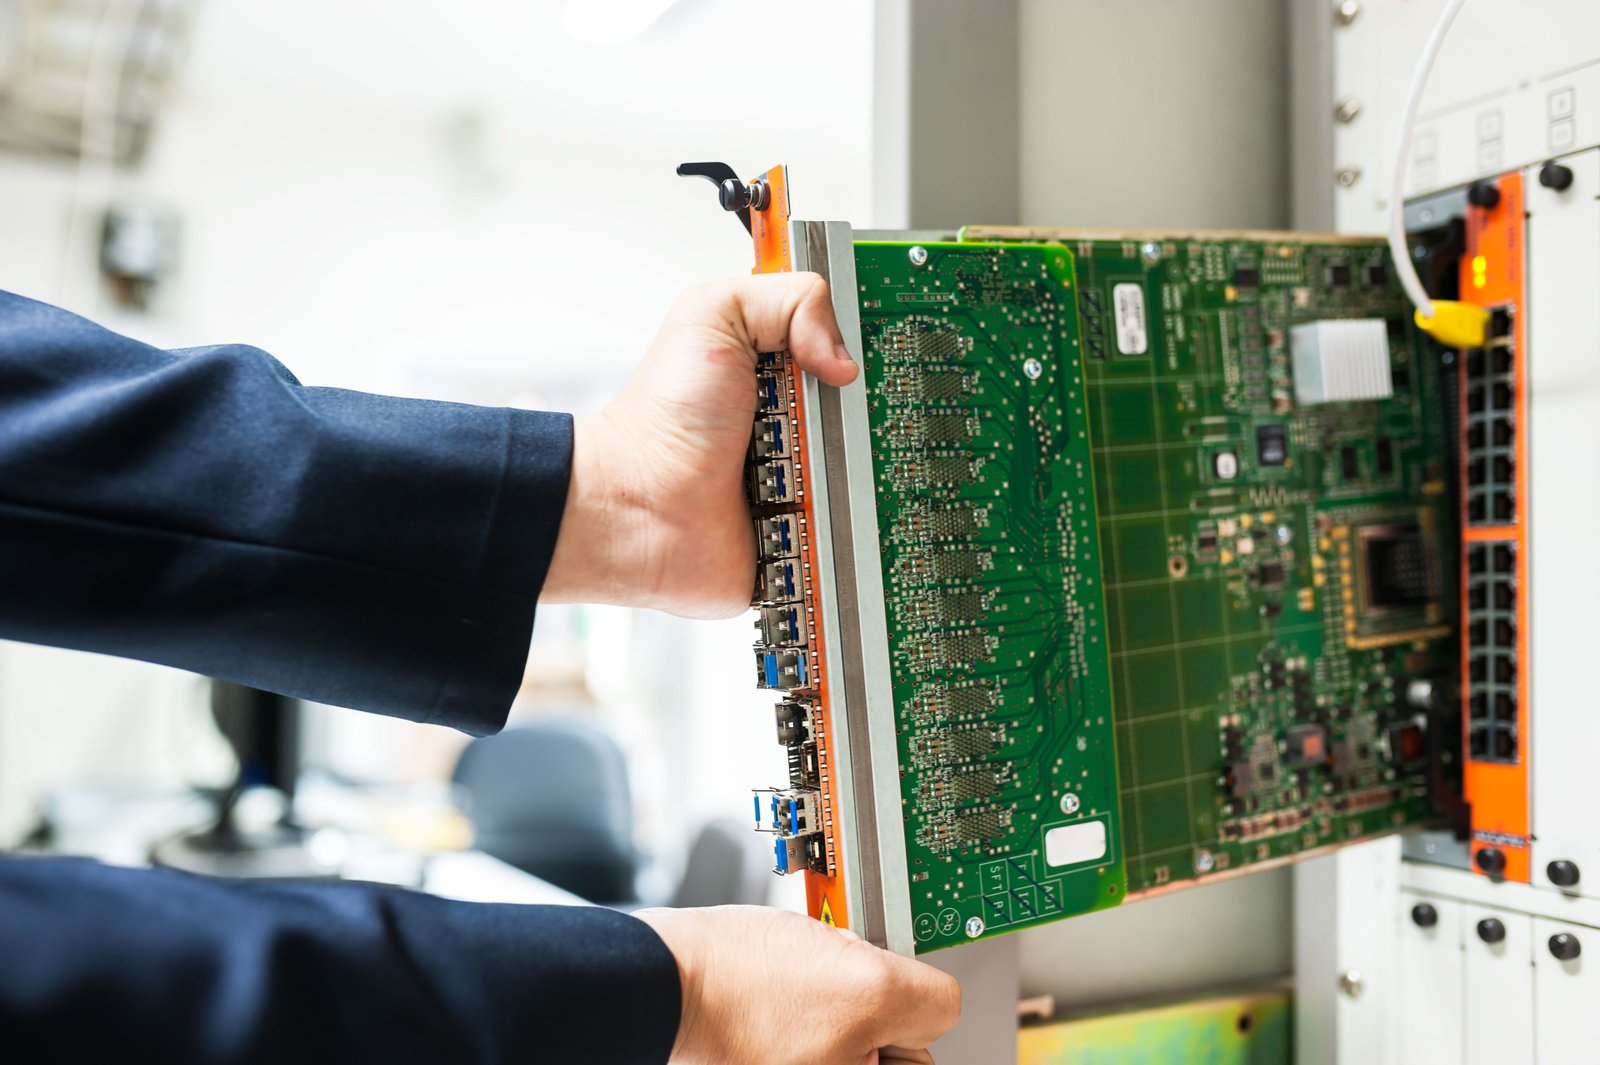
One monthly plan covers the whole layer: provisioning, patching, monitoring, backups, and the 3am pages. No ticket queues staffed by script-readers — an engineer who knows your systems answers.
Monitored infrastructure, 24/7 — the quiet kind of exciting.
24/7 monitoring
Uptime, latency, disk, certificates, backups, security events — monitored around the clock with alerts tuned to real symptoms. Our on-call answers in minutes, not business hours.
Incident response
When things break, we follow runbooks written for your systems, restore service first, and diagnose second. Every incident ends with a prevention task, not just a resolution note.
Patching & maintenance
OS updates, security patches, and dependency upgrades on a schedule you approve — applied, tested, and rolled back automatically if anything misbehaves. You never think about it.
Backup & disaster recovery
Automated backups with tested restores — because an untested backup is a rumor. We verify recovery quarterly and keep your RTO/RPO targets in writing.
How it feels
3:14 AM. We've got it.
This is what an incident looks like when monitoring, runbooks, and automation are doing their job. You wake up to a summary, not a siren.
Hardening checklist
What "hardened" actually means.
Every managed server goes through this baseline before we call it done. No exceptions, no "we'll get to it later."
SSH locked down
Key-only auth, no root login, non-standard port or bastion, fail2ban watching every attempt.
Firewall by default-deny
Only the ports your services need, only from the sources they need them. Everything else is dropped silently.
Secrets out of code
Credentials moved into a vault with rotation. No more .env files in the repo, no more shared passwords in chat.
Updates automated
Security patches applied on schedule with automatic rollback. Vulnerability scans run weekly, findings triaged by severity.
Backups proven
Encrypted, off-site, and — the part most people skip — actually restored and verified on a schedule.
SLAs
In writing.
Promises mean nothing without numbers. These are our standard managed-plan commitments.
- 15-minute response — critical incidents acknowledged by an on-call engineer within 15 minutes, 24/7.
- 99.9% uptime target — measured monthly, reported to you, with credits if we miss.
- 4-hour recovery — maximum time from a confirmed critical failure to restored service.
- Monthly reports — incidents, patches, backup verifications, and upcoming maintenance in plain language.
A note on security work
Deep security engagements — penetration testing, compliance prep, forensic response — are scoped individually and staffed by our dedicated security track. If that's what you need, talk to us directly and we'll tell you honestly whether we're the right fit.
No AI required
The infrastructure health check.
One week. An engineer reviews your servers, backups, patching, access controls, and cloud spend — then hands you a findings document with fixes ranked by risk. No AI, no upsell, no obligation.
- Security posture — open ports, exposed services, access hygiene.
- Backup reality — what actually restores, tested, not assumed.
- Cost review — where the cloud bill leaks and how to plug it.
Response times, published
| Severity | Response | Example |
|---|---|---|
| P1 | < 15 min | Production down |
| P2 | < 1 hour | Degraded, workaround exists |
| P3 | < 4 hours | Non-urgent, scheduled fix |
Written into the managed plan. P1 alerts reach a named engineer — not a queue.
maximum response time on critical incidents — in writing
uptime target, measured monthly — with credits if we miss
maximum recovery time from a confirmed critical failure
of backups with tested restores — untested backups don't count
Commitments, not past results — they're written into the managed plan before we start.
FAQ
Asked before we start.
Yes, to do the job — and we treat it accordingly. Access is provisioned through your own identity provider where possible, logged, and revocable by you at any time. Our contracts include NDAs and data-handling terms as standard.
That's most of our work. We audit first — documenting what's there, what scares us, and what we'd change — then stabilize before optimizing. You get the audit report before committing to a plan.
DevOps builds the release machinery (pipelines, infrastructure as code). SysAdmin keeps the lights on: monitoring, patching, backups, incident response. Build the machinery and keep the lights on are two different jobs — we'll tell you honestly which one you need first.
Yes — many clients keep us as the second pair of eyes and the 3am safety net while their team runs day-to-day. We document everything and train your engineers on the systems we manage.
Plans start with a fixed monthly fee based on server count and complexity — no per-ticket billing, no surprise invoices. The free audit includes a right-sized quote for your infrastructure.
Free · 7 days · yours to keep
Find out what your infrastructure is hiding.
Our free AI audit includes an infrastructure review: security gaps, backup gaps, and single points of failure — ranked by risk, with fix estimates. One week, no cost.