TypeSafe AI's Jev doesn't chat, write, or explain. It decides — returning typed answers with calibrated confidence in 70–500 milliseconds, for fractions of a cent. It's the most important AI infrastructure launch of the year, and it never generated a word of text.
Key takeaways
- Jev ("System One" model, TypeSafe AI, launched Sept 15, 2026) returns typed decisions — Choice, Score, or Yes/No — with probabilities and calibrated confidence, in 70–500ms. No prose.
- Pricing: $0.042 per million input tokens; output is free. The founders: Diogo Almeida (ex-OpenAI, RLHF co-inventor), Erik Gafni, Sasha Sheng. $40M seed led by DCVC.
- Adoption is historic: 1,500+ Hacker News points day one, 13% of paid Vercel AI Gateway teams within 24 hours, integrations with Cloudflare, LangChain, and Langfuse within a week.
- The honest caveats: speed/cost figures are vendor in-house numbers, English-first, known "jaggedness" limitations — and a scam wave of ~670 lookalike domains is already running.
- Bottom line: Jev unbundles the LLM — decisions without the generation tax. Prototype one workflow this week; decide which decisions are load-bearing enough to own.
The biggest AI launch of September did not generate a single word of text. It makes decisions instead.
Jev, the "System One" model from TypeSafe AI, launched September 15, 2026 — and pulled off the most interesting two weeks in AI infrastructure since ChatGPT. You don't chat with Jev. You give it a situation and ask questions; it answers in 70 to 500 milliseconds with a typed result: a choice, a score, or a yes/no value — each with probabilities and a calibrated confidence score. No prose, no explanations.
The quick verdict
| What | Detail |
|---|---|
| Product | Jev — "System One" decision model from TypeSafe AI |
| What it does | Typed decisions (Choice / Score / Yes-No) with probabilities + confidence, in 70–500ms |
| What it does NOT do | Generate text, chat, write, explain in prose |
| Launched | September 15, 2026, after 2 years in stealth |
| Funding | $40M seed led by DCVC (valuation reportedly ~$200M) |
| Founders | Diogo Almeida (ex-OpenAI, RLHF co-inventor), Erik Gafni, Sasha Sheng |
| Price | $0.042 per million input tokens; output free |
| Try it | Playground at console.typesafe.ai; API at api.typesafe.ai; Python + TypeScript SDKs |
| The catch | Vendor figures are in-house, not independent; English-first; API-only early access |
What Jev is — and why everyone is talking about it
Think of everything a frontier language model does, then strip away the words. What remains is judgment: which category, how urgent, how confident, approve or reject. That's the part of AI work that runs inside real software — routing, triage, moderation, guardrails. Until September, the only way to get it was to ask a giant model to write a paragraph and parse it.
Jev is the first serious attempt to productize the decision itself. The launch numbers: well over a thousand Hacker News points on day one; 13% of paid Vercel AI Gateway teams using it within 24 hours (the fastest adoption the gateway has ever seen — 2x the GPT-5.6 family, 6x Fable 5.1; note Vercel made it free on the gateway through September 25); Cloudflare, LangChain, and Langfuse integrating within about a week; roughly 40 million launch-video views in under a week (per Bloomberg); OpenRouter token volume tripling over its first weekend.
The launch-day messaging put it plainly: Jev does not talk — it decides (launch post). Andrej Karpathy framed it as "a point on the LLM Pareto curve" for the regime of "no thinking, single token, low latency" — tapping a latent demand for simple, cheap, fast decision systems.
The name is the tell. Jev is short for William Stanley Jevons, the economist of the Jevons paradox: make a resource dramatically more efficient and consumption explodes rather than shrinking. 400x-cheaper decisions mean a thousand times more automated decisions. That's the bet the name encodes.
How Jev works: a new kind of model, not a smaller one
Jev isn't a distilled chatbot with the words removed. Three components were built for it specifically:
A new model architecture designed for decisions rather than text. A traditional LLM predicts the next token, one word at a time — which is why every answer arrives as a sentence even when all you wanted was "yes." Jev predicts the decision directly.
A parallel sampler that produces all outputs in a single forward pass. No token-by-token generation, no waiting for a reasoning chain to collapse into one word. This is where the 70–500ms latency comes from.
RLCD — Reinforcement Learning for Calibrated Decisions — the training method behind the confidence scores. Most models are overconfident. Jev's confidence is trained to mean something: a 0.33 reading is supposed to behave like 33% accuracy. That calibration is the difference between a demo and a guardrail you can build on.
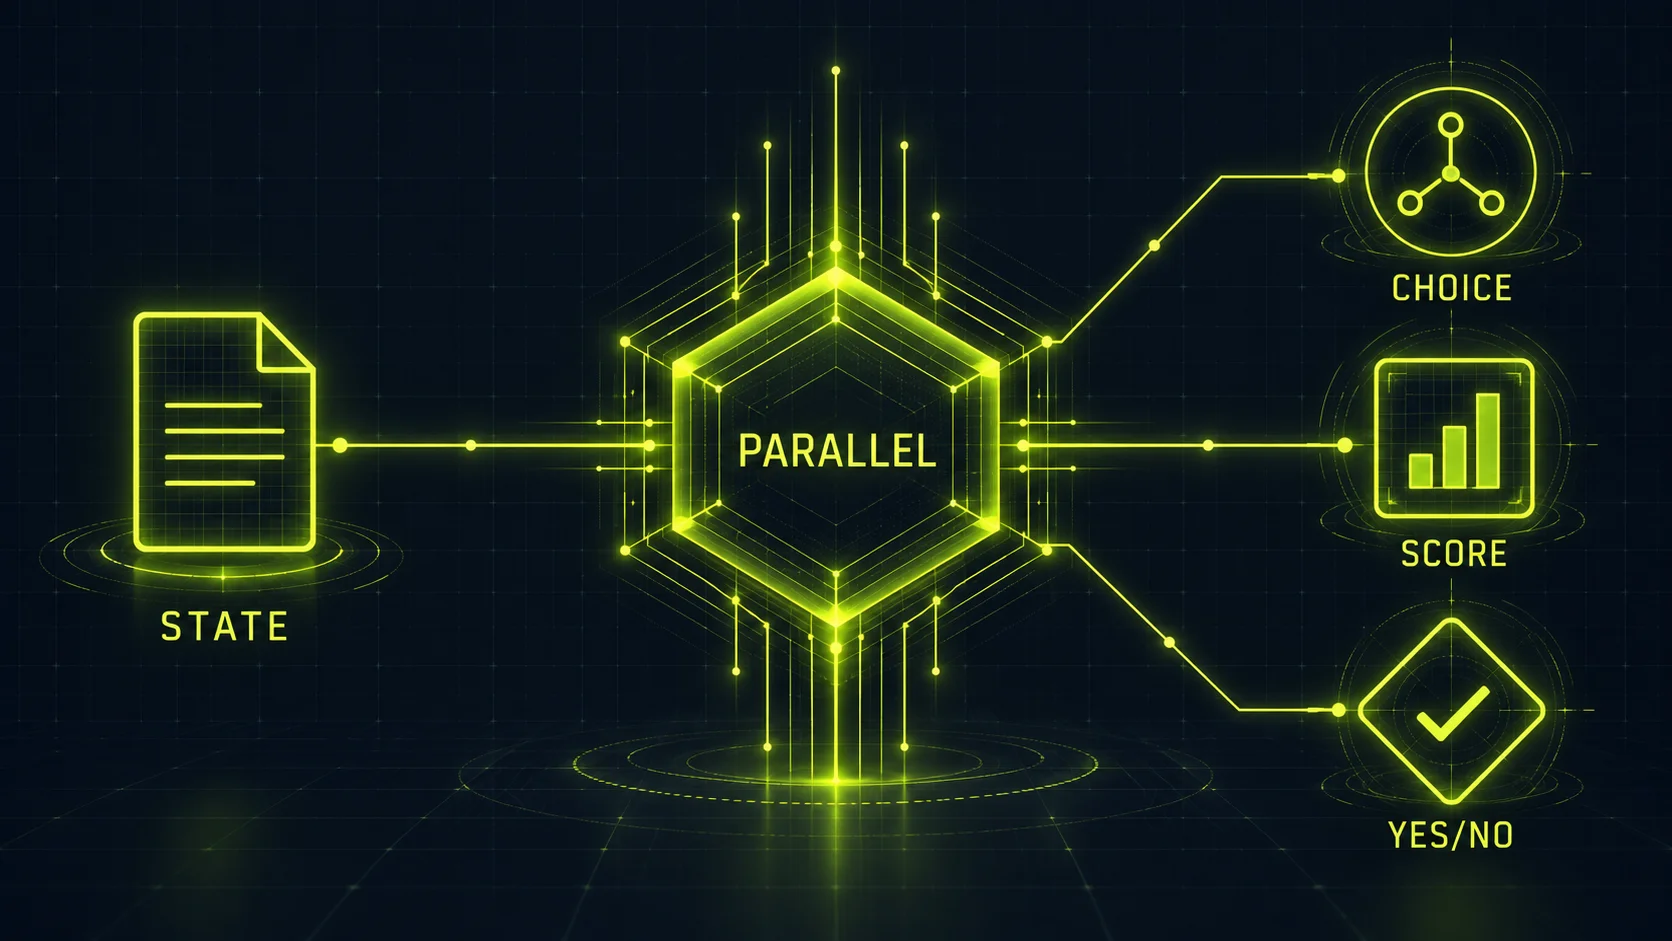
Everything Jev does is built from three typed question types:
- Choice — up to 255 options, probability per option (routing, classification)
- Score — up to 10 levels (frustration, severity, quality)
- Noul — a yes/no value on a continuous [0,1] scale (urgency, risk, approval)
TypeSafe's own documentation is admirably honest about where this breaks: a "jaggedness" document lists literal-reading, context-distraction, adversarial prompts, numerical reasoning, dates, and multi-hop inference as known limitations. The types are guaranteed; factual correctness is not. And the vendor headline figures — up to 193.6x faster and 444.6x cheaper than frontier LLMs on workflow evals — are TypeSafe's own in-house peak numbers, not independent benchmarks.
Jev vs a traditional LLM, head to head
| Traditional LLM | Jev | |
|---|---|---|
| Output | Text, token by token | Typed values: Choice / Score / Noul |
| Latency | Seconds for a decision-sized answer | 70–500ms |
| Cost per decision | Pays for full generated output | $0.042/M input tokens; output free |
| Confidence | Not calibrated; overconfident by default | Trained calibrated via RLCD |
| Failure mode | Confident prose that is wrong | Wrong numbers you can threshold |
| Best use | Anything needing language | Anything ending in a decision |
How to actually use Jev
1. Try the Playground (no code)
The fastest path: the web Playground at console.typesafe.ai. Type a situation ("state") and your questions, pick the question types, and watch decisions come back with probability distributions.
2. The raw API
One endpoint, Bearer auth, a body of `state` plus `questions`:
```
POST https://api.typesafe.ai/v1/systemone
Authorization: Bearer <your-api-key>
```
The canonical example from the quickstart docs — triaging a support ticket with all three primitives at once: a Choice question for department, a Score question for frustration, a Noul question for urgency. The response comes back with probabilities and confidence per question — three decisions, one call, under half a second, no regex on prose.
3. The SDKs
The Python SDK (`pip install typesafe-sdk`) wraps the same call in a `TypeSafeClient`. The TypeScript SDK is MIT-licensed — the practical choice for Node or edge runtimes, with the same fully-typed primitives.
4. The Claude Code skill and OpenRouter
For agent workflows, TypeSafe publishes a skill installable as a Claude Code plugin, so your coding agent calls Jev like any other tool. Jev is also on OpenRouter via a separate decisions endpoint — the route many early adopters took (token volume tripled over launch weekend).
Practical notes before you build
- Versions: use aliases `jev-latest` / `jev-preview` rather than pinning (current pinned: jev-1.13.0)
- Limits: 64k tokens per request; 250k tokens/sec; 1,200 requests/min
- Language: English works best; anything else is experimental
- Pricing math: a million ticket-sized decisions costs roughly four cents of input
What it changes at the architecture level
The best description circulating is short: Jev is the `if` statement that understands text.
Every production agent today is held together with prompts. A workflow needs to decide something, so it calls a frontier model, waits for 500 tokens of chain-of-thought, and extracts the word "yes" from paragraph three. That's the most expensive `if` statement in computing history — slow, metered per token, and fragile, because prose is not a type system.
Two patterns are emerging:
Agent routing — "Jev Router." Jev sits at the front door and picks which model handles each request: cheap and fast for easy cases, frontier only for hard ones.
Guardrails that can actually act. A shell guardrail asks Jev whether a command is reversible before it runs. An ambiguous `rm -rf` came back with a low-confidence "irreversible" reading — so the system asked a human instead of guessing. The model knows what it doesn't know, and the software branches on it.
What people are actually building
Two weeks after launch, hundreds of community projects reference Jev:
- Document intelligence at absurd prices: 1,018 papers sorted into 24 themes for $0.08
- Founder sourcing: resumes run against 6,245 YC companies in 25 seconds for $0.37
- Hiring pipelines: Metaview put Jev inside its recruiting agents — candidate searches ~10x faster at the same accuracy
- Agent infrastructure: one developer reported 71% less dispatch cost routing agents through Jev
- Jev UltraFast: turns web pages into tables of clickable items by classifying every element in parallel
The platform integrations tell the enterprise story: Vercel AI Gateway and Cloudflare's AI Gateway within days. The decision model is being sold as infrastructure, not an app.
Honest pros and cons
Why it's genuinely exciting: sub-second decisions mean the decision loop can live inside interactive software, not just batch pipelines. At four cents per million input tokens with free output, decisions become too cheap to meter. Typed outputs kill a whole class of parsing bugs. And calibrated confidence enables guardrails that branch on uncertainty instead of guessing.
Why you should stay skeptical: the 193.6x/444.6x figures are vendor numbers, not independent benchmarks. The novelty is contested — Arena's CEO has publicly questioned what distinguishes Jev from a standard zero-shot classifier. Jaggedness is real (TypeSafe's own docs list the limitations). It's English-first and early-access. And a type system doesn't fix bad data: Jev will give you a beautifully typed, calibrated answer to a badly framed question.
A security warning before you try it
Success attracts parasites. Within eight days of launch, roughly 670 "jev"-branded domains had obtained TLS certificates — and some were lookalike storefronts charging up to 11.5x the official rate while proxying requests to TypeSafe, meaning your proprietary prompts pass through a stranger's server. At one point the top Google result for "jev ai" wasn't TypeSafe at all (GBHackers).
Get your API key only from TypeSafe's own console. Never type proprietary data into a third-party "Jev playground." Check the domain character by character.
Rent or own?
An open-weights distilled model landed within two weeks: AutoTrust AI's JEV-27B (Apache 2.0), running on a single B200/H100, at effective benchmark parity with TypeSafe's Jev 1.13 (84.07% vs 83.85% across six benchmarks, per AutoTrust's own runs).
Jev-the-API is rented infrastructure: TypeSafe sets the price, the roadmap, the off switch. JEV-27B-the-weights is ownable: your servers, your data plane, your version pin. Prototype on the rented API; plan the owned path for anything load-bearing.
The bottom line
Strip the hype and Jev is still the most important AI launch of the year, for one reason: it unbundles the LLM. For three years we bought generation and decisions as a bundle, because the only machine that could decide was the machine that talked. Jev separates the two — and the economics of the separated decision are devastating to the bundle.
Give AI a return type and everything changes. The founders named it for the Jevons paradox, and they understand the implication: 444x-cheaper decisions don't mean we spend less on decisions. They mean the thousand tiny judgment calls inside company software that were never worth automating — every ticket, every alert, every permission check — get automated.
If you run any system that makes repeated judgments on text — support, moderation, routing, hiring, fraud, agents — prototype one workflow this week. The Playground takes thirty seconds. And decide now which of your decisions are load-bearing enough to own, because the rent-vs-own clock on this category is already ticking.
FAQ
What is Jev?
Jev is TypeSafe AI's "System One" decision model (launched Sept 15, 2026). Instead of generating text, it returns typed decisions — Choice, Score, or Yes/No — with probabilities and calibrated confidence scores, in 70–500ms, at $0.042 per million input tokens with free output.
How is Jev different from a regular LLM?
A regular LLM predicts text token-by-token — even when all you wanted was "yes." Jev predicts the decision directly via a parallel sampler (one forward pass, no token generation), with confidence trained to be calibrated (RLCD). Result: ~100x faster, ~400x cheaper per decision, and outputs you can threshold in code.
What are Jev's limitations?
TypeSafe's own docs list literal-reading, context distraction, adversarial prompts, numerical reasoning, dates, and multi-hop inference as known "jaggedness." The types are guaranteed; factual correctness is not. It's English-first, and the headline speed/cost figures are vendor in-house numbers awaiting independent replication.
Is Jev safe to try?
The product — yes, via TypeSafe's own console. The ecosystem — carefully: ~670 lookalike "jev" domains appeared within eight days of launch, some proxying prompts through strangers' servers at 11.5x markup. Get keys only from console.typesafe.ai and check domains character by character.
Sources
Sources
- TypeSafe AI documentation: Jev introduction and quickstartdocs.typesafe.ai
- TypeSafe AI official launch post on X (2.2K likes, 273K views)x.com
- TypeSafe AI out-of-stealth announcement on X (501K views)x.com
- Most-shared community explainer of Jev on X (801 likes)x.com
- TypeSafe AI announcement of Vercel AI Gateway integrationx.com
- TypeSafe AI announcement of Cloudflare AI Gateway integrationx.com
Want to know what this means for your stack? A free AI audit maps your workflows and shows where automation pays off — in your numbers, not ours.