Anthropic's new flagship model costs about 40% less per task than its predecessor — while matching the company's top tier on performance. The AI price war has officially entered its comparison-shopping phase.
Key takeaways
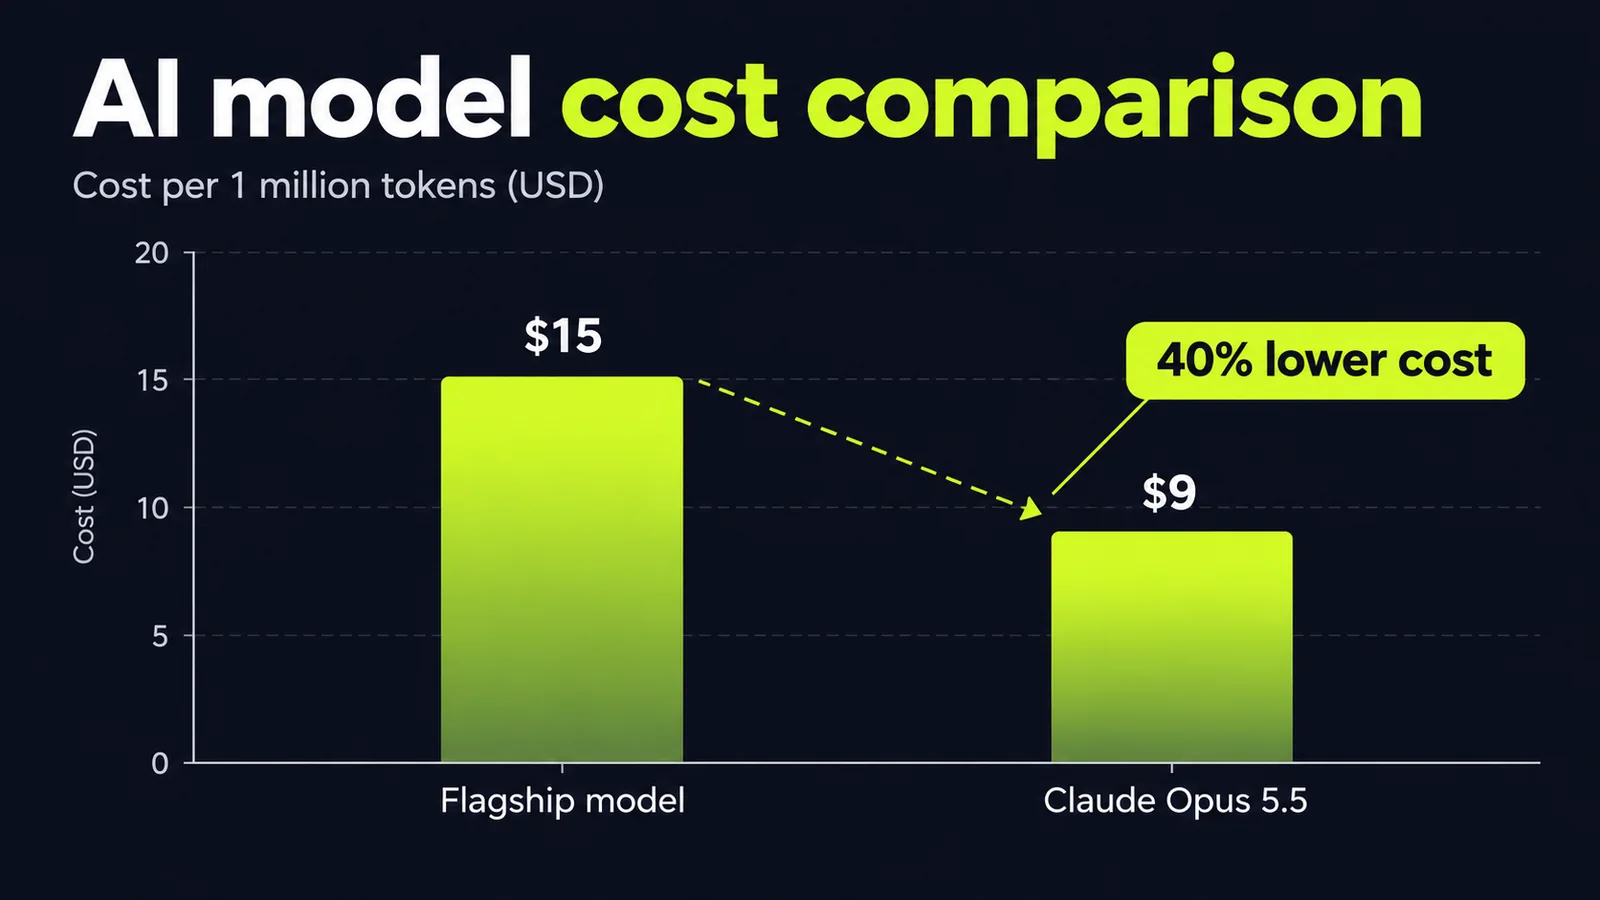
- Claude Opus 5.5 is priced at $4 per million input tokens and $20 per million output tokens — roughly 40% cheaper per completed task than Opus 5.
- Anthropic says it performs on par with its highest-tier model, Claude Fable 5.1, on most tasks — and generates output 30%+ faster.
- The deepest cut is in prompt caching: cache reads fell 60% to $0.20 per million tokens, which matters most for long agentic workflows.
- Safety improved too: 85% less likely than its predecessor to attempt bypassing its prescribed boundaries, per Anthropic.
- Bottom line: if you shelved an AI pilot on cost grounds, the math has changed — re-run the ROI.
Anthropic released Claude Opus 5.5, its new flagship model. The detail that matters for anyone running a business is the price tag.
For two years, each new model generation asked businesses to pay more for more capability. Opus 5.5 breaks that pattern: comparable top-tier capability for meaningfully less money. The question is no longer just "how smart is it" — it's "how much does each completed job cost."
What actually changed
Opus 5.5 is the first release in a new Claude 5.5 family. It launched simultaneously across the Claude apps, the Claude API, and all three major clouds — AWS, Google Cloud, and Microsoft Azure. Sonnet 5.5 and Haiku 5.5 are expected in the coming weeks, per TechSpecSmart's breakdown.
On performance, Anthropic's headline claim — reported by Reuters — is that Opus 5.5 performs on par with Claude Fable 5.1, the company's highest-tier model, on most tasks. It's also faster, with output generation reportedly 30%+ quicker than Opus 5, and Anthropic says it writes more clearly.
On safety, Anthropic reports the model is 85% less likely than Opus 5 to attempt bypassing its prescribed boundaries. It ships with Fable-class safeguards covering cybersecurity, biology, and distillation-related work.
The context matters. This is the first major release since Anthropic's CEO publicly called for the industry to slow capability advances so safety work could keep pace. The company's answer, as Runtime Wire's analysis puts it: a model that advances efficiency and oversight rather than raw capability — more external evaluation, automated behavioral testing, and guardrails, including routing some sensitive requests to older models.
The price story is the real headline
The per-token cuts are straightforward:
| Metric | Opus 5.5 | Opus 5 (predecessor) |
|---|---|---|
| Input tokens | $4 / million | ~$5 / million |
| Output tokens | $20 / million | ~$25 / million |
| Cache reads | $0.20 / million (60% cut) | $0.50 / million |
| Typical cost per task | ~40% lower | baseline |
But the structural change runs deeper than the sticker price. Digital Applied's line-by-line analysis notes that cache reads dropped to just 5% of the input price, versus 10% on most Claude models.
Why does that matter? Anthropic says cache reads make up the majority of agentic and coding workload costs. AI agents re-read the same context repeatedly as they work through multi-step tasks. Cheaper cache makes long agentic runs dramatically cheaper.
The 40% lower cost-per-task claim isn't just cheaper tokens. It's the model needing fewer tokens — and fewer tool calls — to finish the same job.
Performance where it counts for business
Vendor benchmarks deserve a skeptical eye. But the pattern of this release favors what businesses actually buy: agentic coding, long-horizon work, and reliability.
Anthropic reports Opus 5.5 at 66.4% on Terminal-Bench 4.0, an agentic coding benchmark — reportedly the highest of the five models it compared. An independent Artificial Analysis Intelligence Index score of 54 puts it in the top three on that leaderboard.
More telling is the real-world work Anthropic's early testers shared:
- A 680,000-line code migration completed in less than a day
- Load-time fixes that succeeded on 39 of 40 pages of a web app without breaking existing behavior
- A 200,000-line codebase audited and fixed in under three hours — where Opus 5 had needed over 20 hours and 2.5x the tokens
These are vendor-shared examples, not independent audits — take them as directional. But the direction is consistent: this model is built for long, expensive jobs (code migrations, system refactors, multi-step agent workflows), and it's specifically cheaper and faster at exactly those.
The comparison-shopping phase
Opus 5.5 didn't land in a vacuum. The same week, OpenAI released GPT-6 Sol and Luna — its own pair of models pitched on the same "more for less" axis.
Competition on cost-per-completed-job is now the front line of the model race, not raw benchmark leadership. That turns the question from "can we afford to automate this?" into "can we afford not to check whether the math works now?"
Pilots that failed on cost twelve months ago deserve a second look.
What this means for your business
Re-run the ROI on paused automation projects. If you shelved an AI pilot because the token bill was too high, 40% lower per-task costs plus faster completion may flip the math — especially for long agentic workflows like support triage, document processing, and code migration.
Audit your model tier. If you're paying top-tier prices on work Opus 5.5 can now handle at half the cost, you're overpaying. Review which workflows genuinely need the highest tier. And if your workloads re-read context repeatedly, prompt caching just became a pricing superpower — make it a standard habit.
Treat speed as a feature. A model that's 30%+ faster doesn't just cost less per task — it changes what's feasible in interactive workflows. Customer-facing copilots, real-time summarization, and live review tools all get more responsive without paying a premium tier.
Build for model mobility. With every lab cutting prices on a weekly cadence, hard-coding your stack to one model is a liability. Design automation around swappable model endpoints, versioned prompts, and evaluation benchmarks you own — so the next 40% price cut benefits you on day one.
Don't skip the safety side. The 85% reduction in boundary-bypass attempts and Fable-class safeguards matter for regulated or customer-facing use. But "better than the previous model" isn't "safe for your use case." Production deployments still need your own guardrails: scoped tool permissions, human review on irreversible actions, logged outputs.
The bottom line
Frontier AI is getting cheaper faster than most businesses are updating their assumptions. The gap between "what the models cost" and "what you think the models cost" is where competitive advantage now hides.
Every week, the cost structure of AI changes — and most businesses still plan with last year's numbers. A free AI audit maps your current workflows against today's model pricing, finds the automation opportunities with the highest ROI, and shows exactly where cheaper models change the math. Take the free AI audit and get a clear, senior-engineering-grade picture of what automation should cost you now.
FAQ
How much cheaper is Claude Opus 5.5 really?
About 40% less per completed task than Opus 5, per Anthropic. Per-token prices are $4/M input and $20/M output (roughly 20% below Opus 5, roughly half of Fable 5.1) — but the bigger driver is efficiency: fewer tokens and fewer tool calls per job, plus a 60% cut to cache-read pricing.
Is Opus 5.5 as capable as the top-tier models?
Anthropic claims it performs on par with Claude Fable 5.1 — its highest-tier model — on most tasks. Independent signal: an Artificial Analysis Intelligence Index score of 54, top-three on that leaderboard, and 66.4% on the Terminal-Bench 4.0 agentic coding benchmark.
What workloads benefit most from the new pricing?
Long agentic and coding workflows: code migrations, system refactors, multi-step agent runs, support triage, document processing. These re-read context heavily, so the 60% cache-read cut compounds the savings.
Should businesses switch models immediately?
Not blindly. Re-run the ROI on paused pilots, audit which workflows genuinely need top-tier models, and design for model mobility — swappable endpoints and owned eval benchmarks — so you capture the next price cut too.
Sources
Sources
- Anthropic Unveils Claude Opus 5.5reuters.com
- Claude Opus 5.5: Launch, Pricing and Benchmarksdigitalapplied.com
- Anthropic Launches Claude Opus 5.5 With Lower Prices and a Top-Three Benchmark Scoreruntimewire.com
- Anthropic Launches Claude Opus 5.5: Benchmarks and Pricingtechspecsmart.com
Want to know what this means for your stack? A free AI audit maps your workflows and shows where automation pays off — in your numbers, not ours.